Beyond RGB: The Rise of Hyperspectral Rendering and Synthetic Data
Hyperspectral and multispectral imaging expose what RGB cannot: the continuous variation of light across wavelengths.
With What Accuracy Levels Can We Get Away in Computer Vision?
There’s no magic number. No single threshold that separates “good” from “bad.” 80%, 90%, 99% — these values mean nothing until you define the context: dataset complexity, operational risk, and task type.
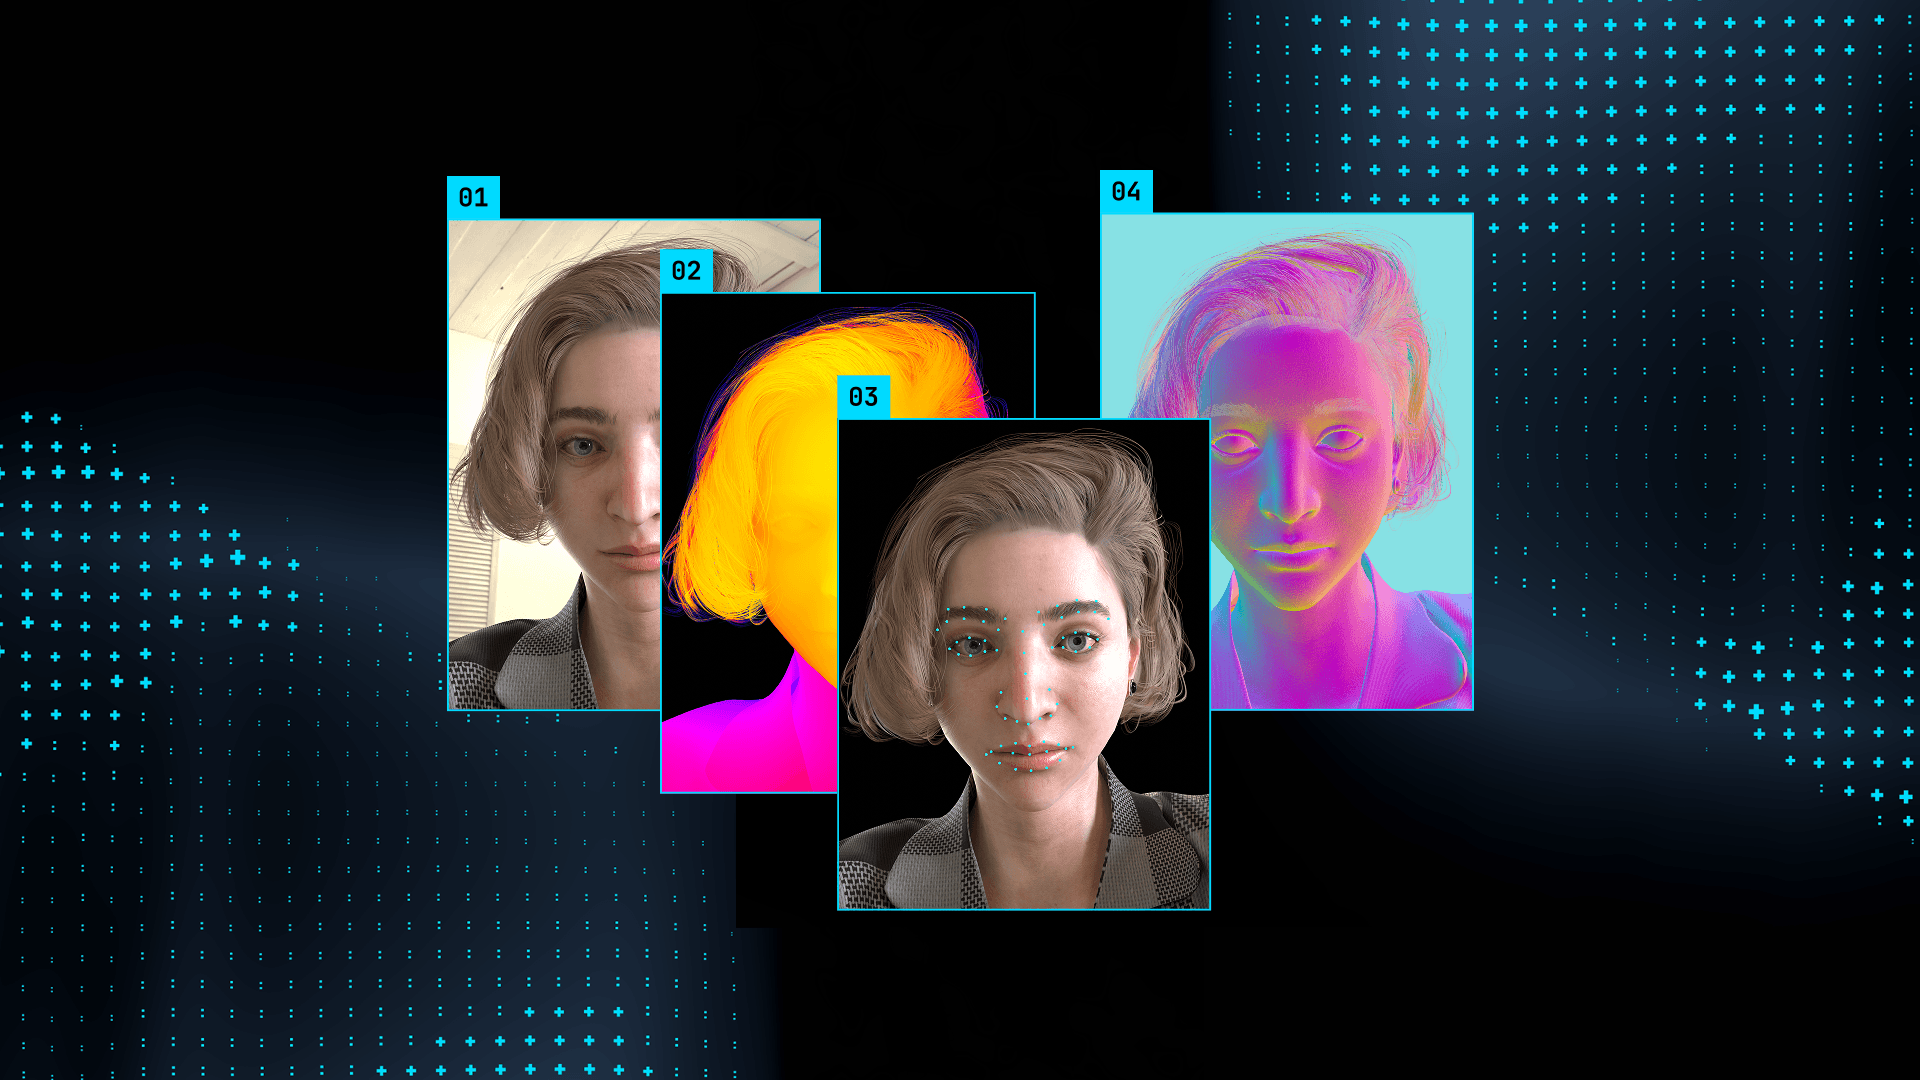
Synthetic Data vs Real Data – How to Choose?
Learn when synthetic or real data works best, how each affects AI performance, and why a hybrid approach gives the most reliable and scalable machine learning results.
Why do we need synthetic data?
Discover how synthetic data steps in when real-world data falls short.
Synthetic Data in 2030 – Technologies, Shifts and Challenges Ahead
See how synthetic data will evolve by 2030, which technologies will drive growth, and what challenges and standards will shape the next decade of AI development.
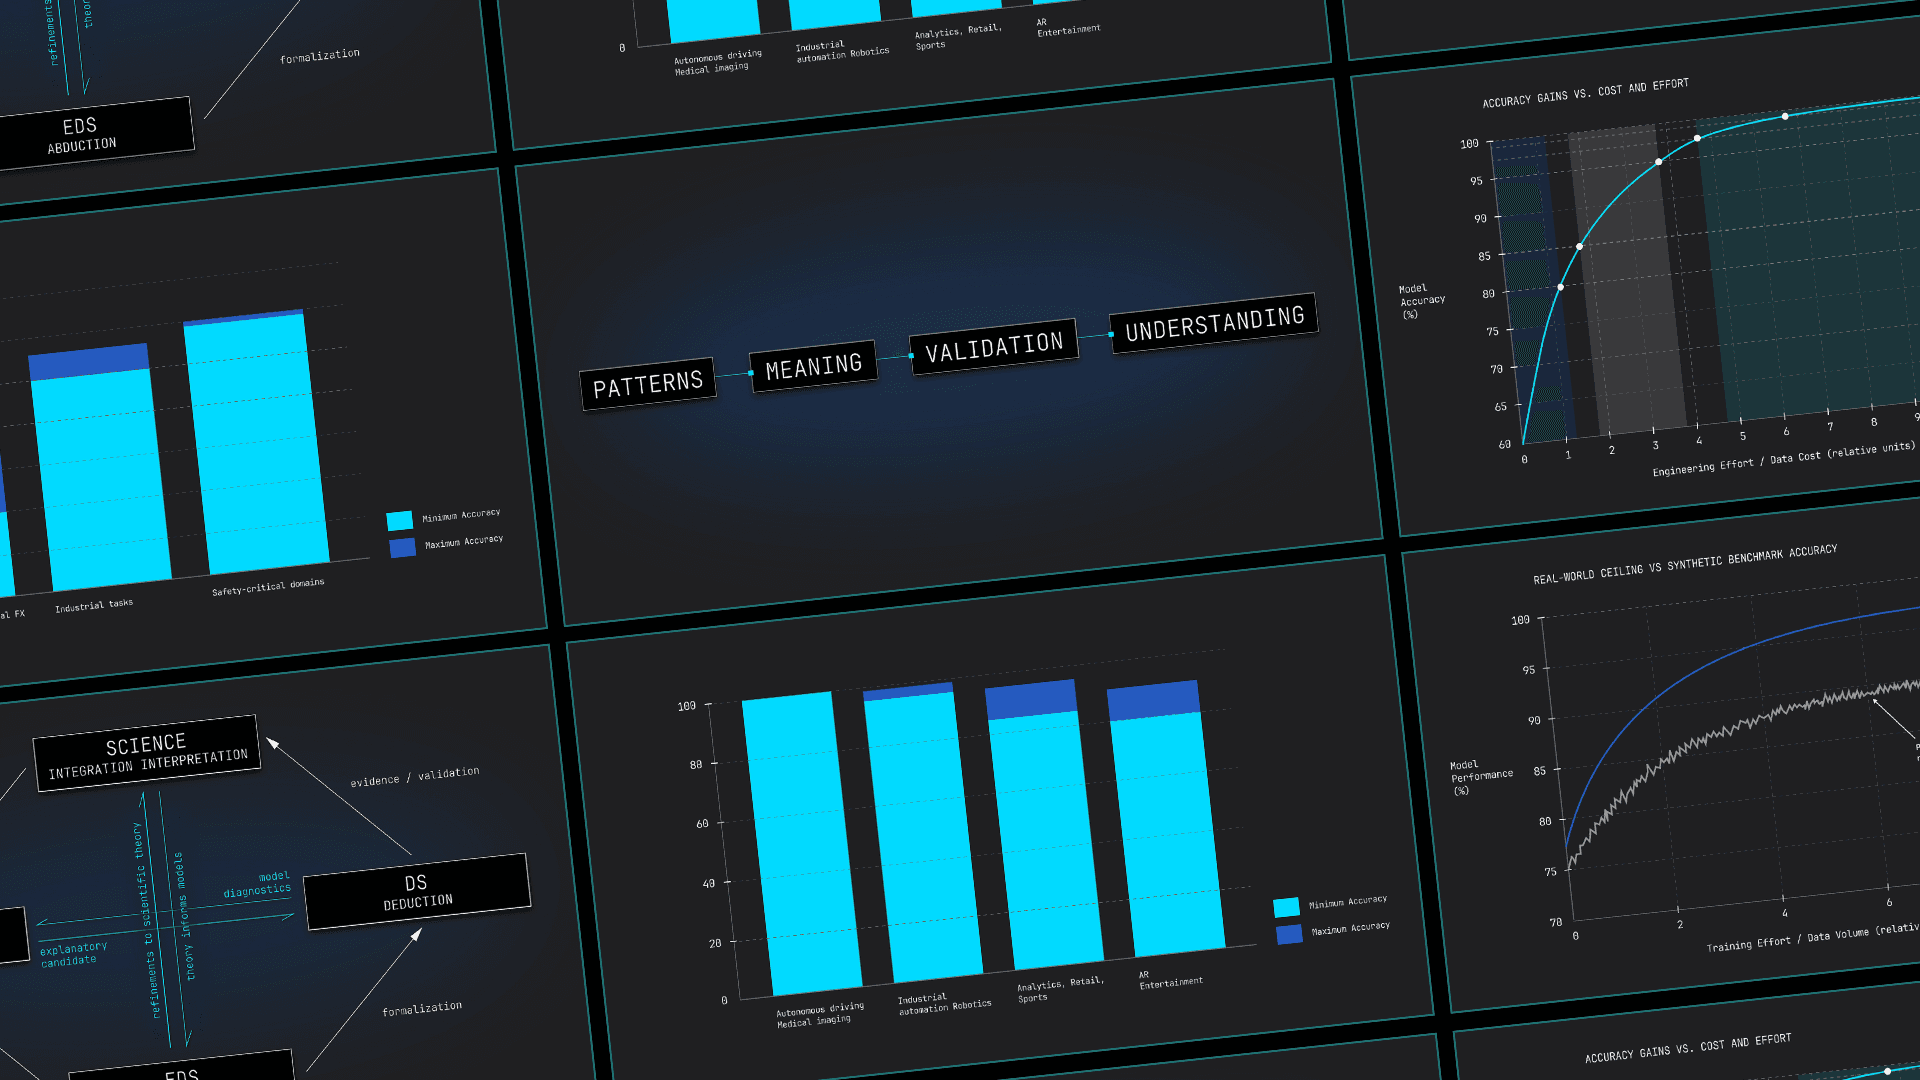
7 pillars of trust: how to build AI you can truly trust?
Check out the major criteria every trustworthy AI system should meet, and why they matter for building reliable and responsible models.
How Synthetic Data Solves Rare-Event Modeling Problems?
Learn how synthetic data fills gaps in rare-event modeling, strengthens AI robustness, and safely simulates edge cases that real datasets can’t capture.
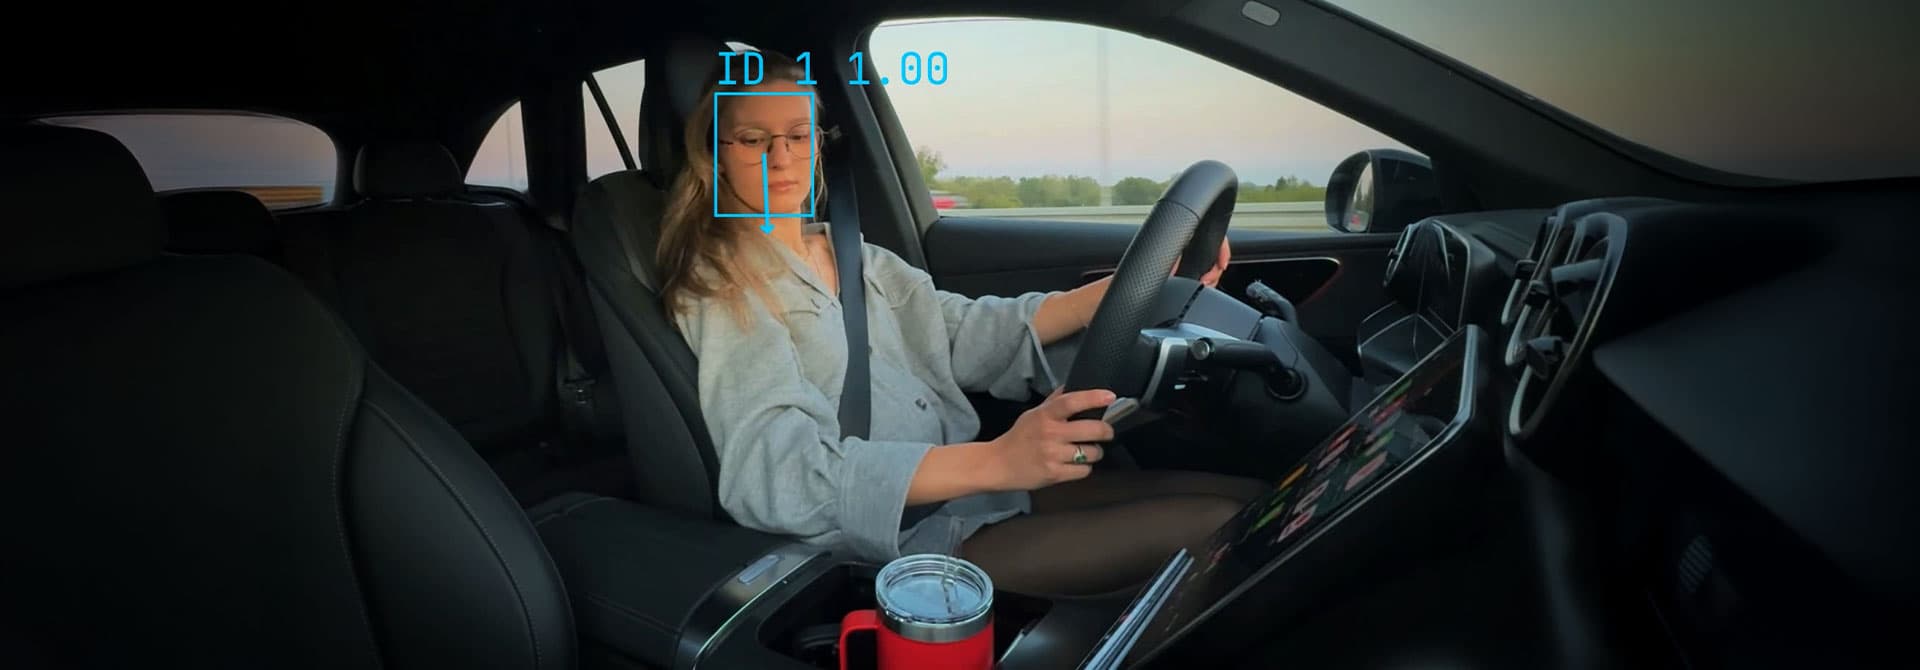
Synthetic Data 101: Training CV Models Without Huge Real Datasets
Real-world data is expensive, repetitive, and misses the moments that matter most. SKY ENGINE AI generates lifelike synthetic data — complete with perfect labels and realistic physics — in hours, not months. From cars to drones to robots, it helps AI models see every scenario before they meet the real world.
Is Your Synthetic Data Trustworthy? Key Metrics and Tests
Learn how to assess synthetic-data quality with essential metrics, stress tests and validation tools, and discover how to build trusted datasets for real-world AI deployment.
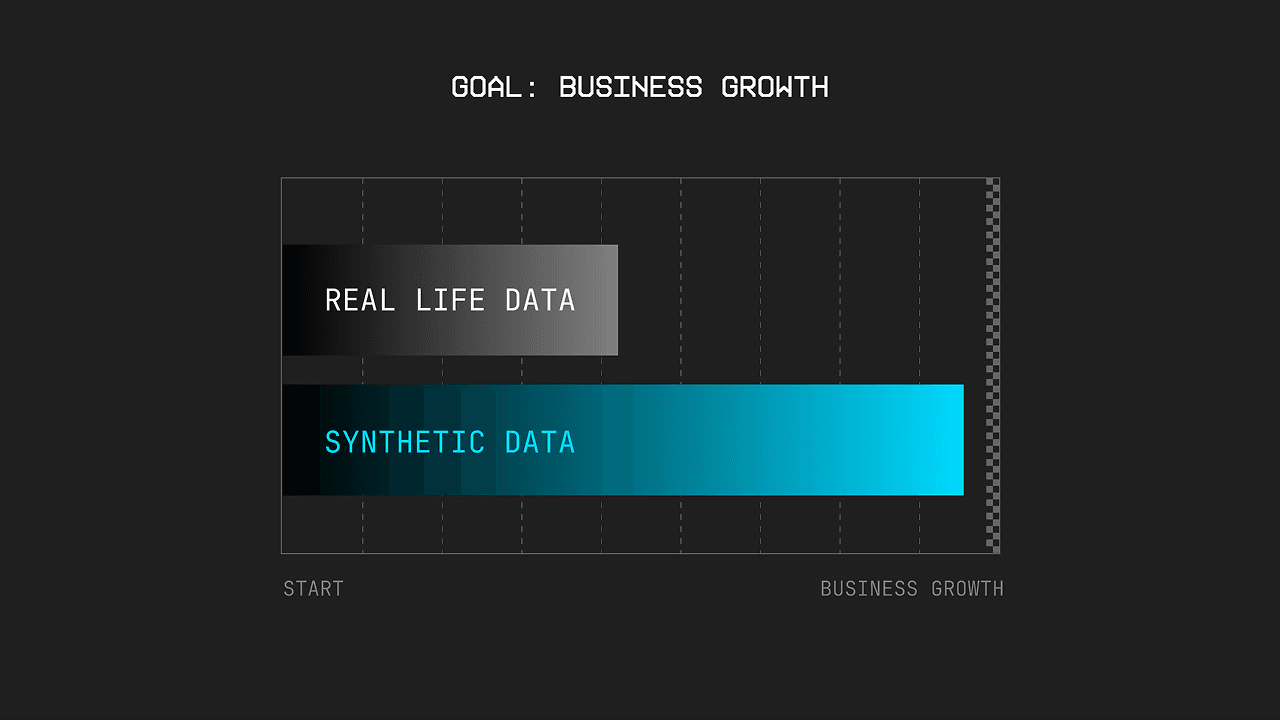
Why Waiting for Real Data Is the Fastest Way to Lose in AI
To remain competitive, organizations need the ability to scale efficiently, integrate seamlessly, and adapt swiftly. Synthetic data plays a key role in enabling this kind of resilience and agility.
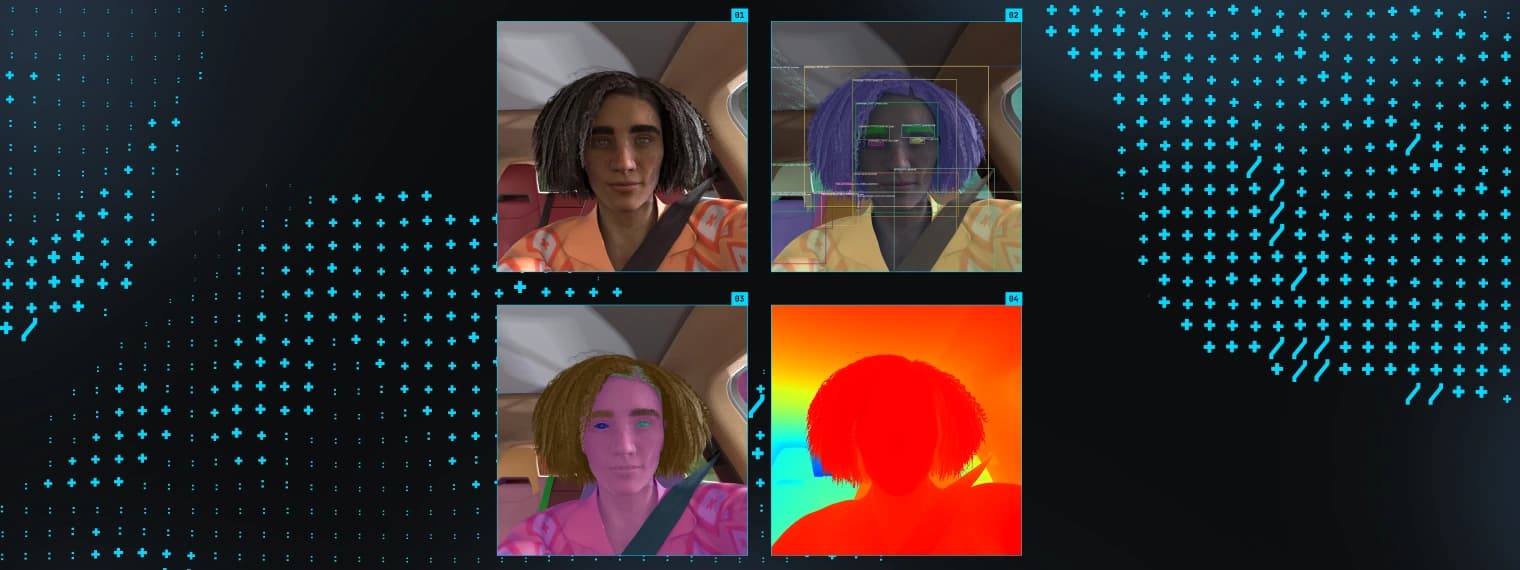
Functionality Wins: Why Purpose‑Built Synthetic Data Beats Pretty Pictures
While photorealistic synthetic data may look impressive, purpose-built functional datasets with parametric variation, perfect annotations, and domain randomization consistently outperform pretty visuals in training robust computer vision models. For real-world AI deployment, precision-engineered synthetic data that prioritizes teaching efficiency over aesthetic appeal delivers better model performance at lower computational costs.
Synthetic Data and GDPR
Learn how artificial data can help protect privacy in the age of AI.